Break language barriers in every conversation.
Spoken.ai is a next-generation real-time voice translation meeting platform. Participants join video calls speaking naturally in their preferred native tongue, while attendees hear simultaneous neural voice synthesis in their respective target languages with under 500ms pipeline latency. Built without bloated client downloads, Spoken.ai runs smoothly directly in modern web browsers.
Product In Action
Interactive Walkthrough & Demo
Experience how Spoken.ai processes real-time audio streams, preserves vocal inflection, and displays dual synchronized subtitles.
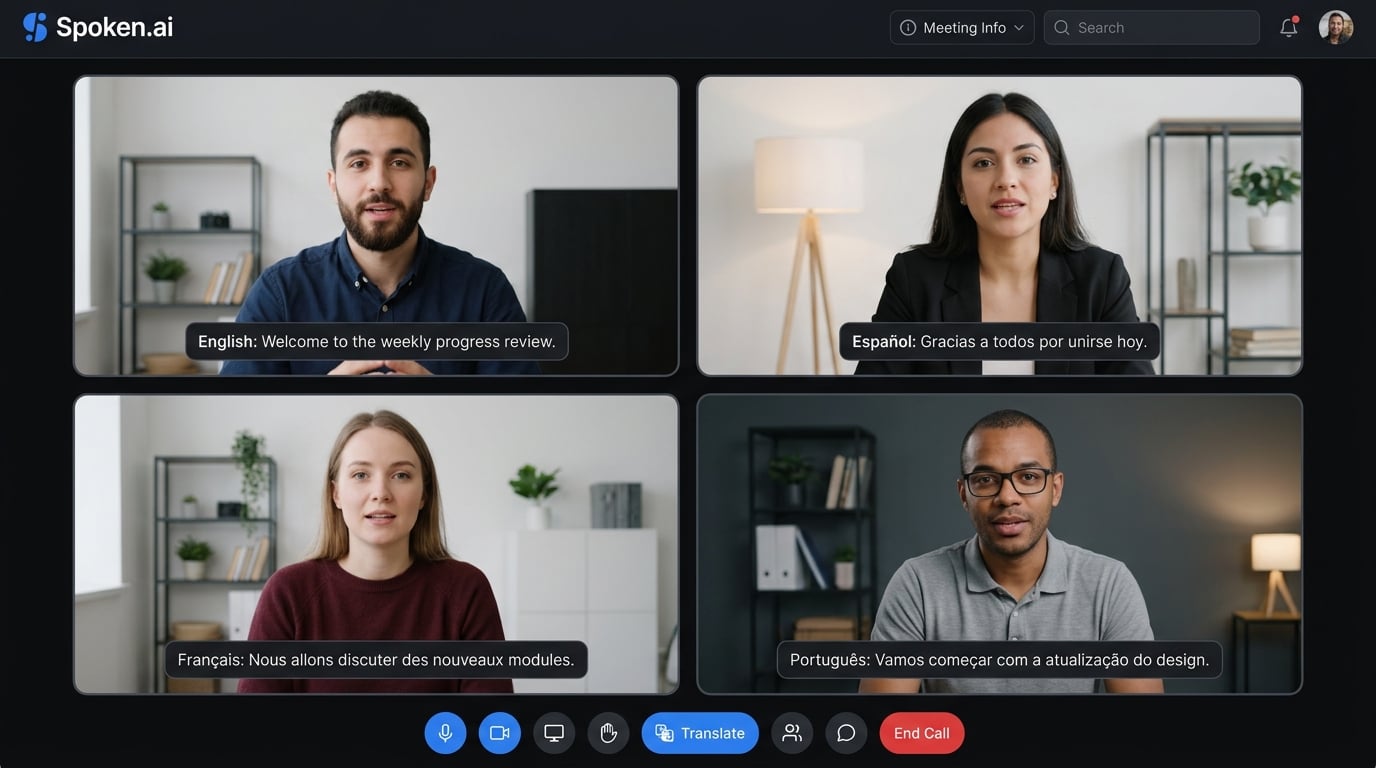
Spoken.ai In Action — Real-time Multilingual Call Walkthrough
Product walkthrough video recording slot (1:45). Place a video in assets or configure videoUrl in projects.ts to stream your real recording.
Engineered For Clarity
Key Capabilities
A comprehensive voice intelligence platform built from the ground up for zero-friction global collaboration.
Sub-500ms Speech Translation
Direct neural translation pipeline streaming audio frames with near-instant turnaround so conversations flow naturally.
Voice Identity Preservation
Synthesizes translated speech matching the original speaker’s vocal tone, pitch, cadence, and human warmth.
Dual Transcriptions & Captions
Follow along with real-time bidirectional captions showing both original and translated text side-by-side.
Zero Download WebRTC Architecture
Runs directly in any modern browser on desktop or mobile. No heavy desktop installations required.
Enterprise-Grade Room Privacy
End-to-end encrypted peer data with zero persistent audio recording unless explicitly enabled by hosts.
Multi-party Scalability
Powered by Kafka message queues and optimized selective forwarding units for multi-participant rooms.
Visual Tour
Interface & Screenshots
Explore Spoken.ai in action: real-time meeting room layout, bidirectional captions, and voice controls.
Engineered For Performance
Performance & Reliability
Engineered for natural conversational speed, rock-solid uptime, and privacy by design.
Sub-500ms Audio Pipeline
Near-instant neural synthesis ensures dialogue flows without awkward pauses or delay.
Zero Installation (Web-Native)
Runs directly in Chrome, Safari, Firefox, and Edge. Zero heavy client downloads required.
Voice Identity Retention
Synthesized audio retains the natural vocal warmth, inflection, and cadence of the speaker.
Ephemeral Memory Privacy
Incoming audio packets are processed in-memory and discarded. Zero persistent audio storage.